Publications
* equal contribution. Full list also on Google Scholar.
Journal Articles
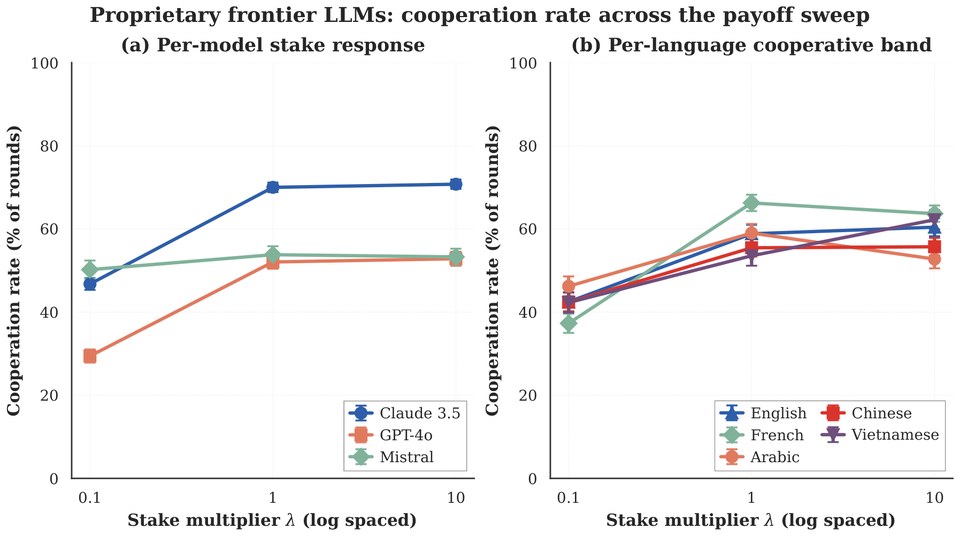
How the size of the stake and the prompt language change the strategies LLM agents play in cooperation dilemmas. Earlier title: More at Stake.
Conference Papers
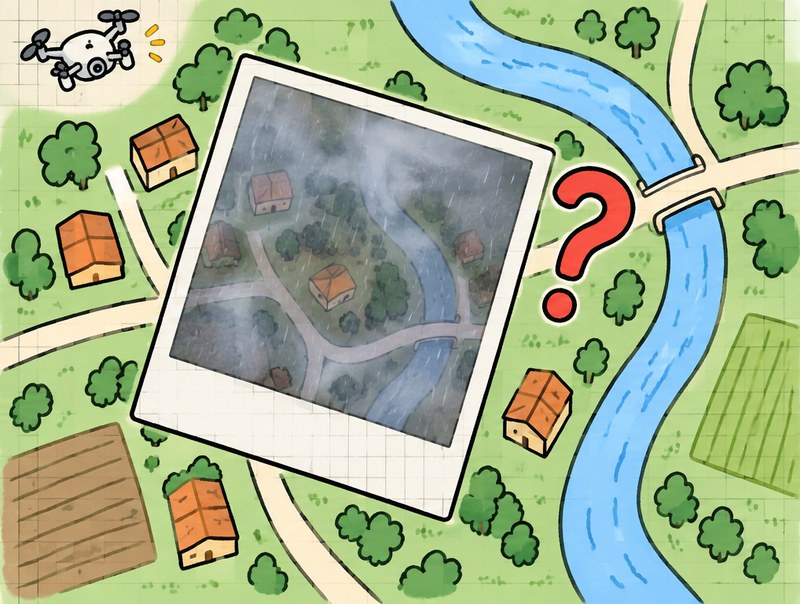
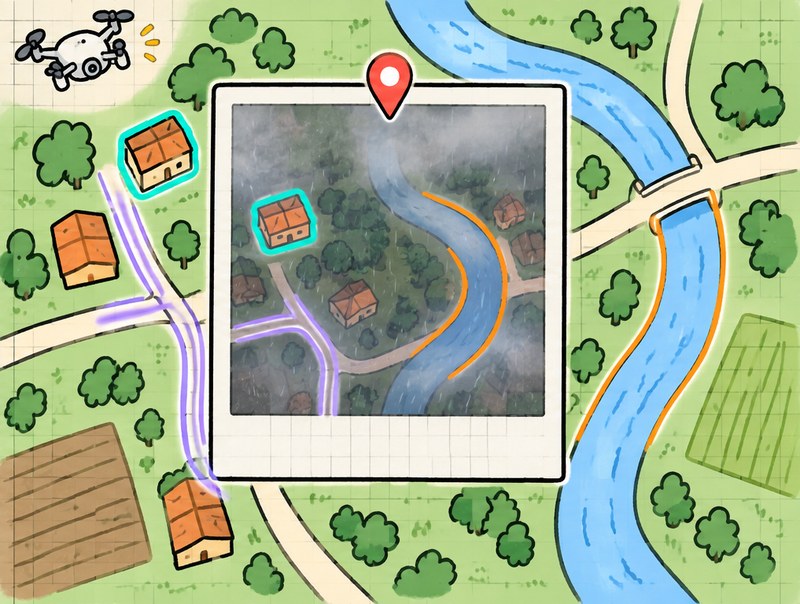
SkyPart: a lightweight prototype-based semantic-part head on a DINOv2 ViT that matches drone views to satellite tiles under fog, rain, snow and darkness. State of the art on weather-robust drone-to-satellite geo-localization with the fewest parameters among top methods.
Streaming decision trees that learn new classes online from a data stream, with split decisions backed by a McDiarmid concentration bound and knowledge inherited across splits.
Holistic training with a slot-attention router, then compositional inference that scores queries part by part, so a continual few-shot learner generalizes to unseen combinations of known parts.
Aligns a frozen LLM to the moral preferences of a country without training: country-conditioned personas vote, and only the decisions they agree on are kept.
The benchmark paper of the NeurIPS 2025 Mouse vs. AI competition, co-authored with the organizers as a member of the first-place team.
Competition, Challenge & Shared-Task Papers
1st Place (tied), Task 11 Subtask 1, perfect score 100.0
Separates logical form from content so an LLM judges whether a syllogism is valid, not whether it sounds plausible: structure-disentangled prompting, valid-to-invalid counterfactual augmentation, and high-rank QLoRA adaptation.
Tied 5th, Task 12 (score 0.90)
Finds the most plausible cause of a real event from retrieved documents: hybrid BM25 plus dense retrieval for causal keywords, then LoRA on both attention and MLP layers of a 32B model with 0.81% trainable parameters.
MEMRES: A Memory-Augmented Resolver with Confidence Cascade for Agentic Python Dependency Resolution
Winner, FSE-AIWare 2026 Agentic Python Dependency Resolution Competition
An agentic resolver that repairs broken Python environments with a self-evolving memory, a confidence cascade over version candidates, and a build-and-reflect loop.
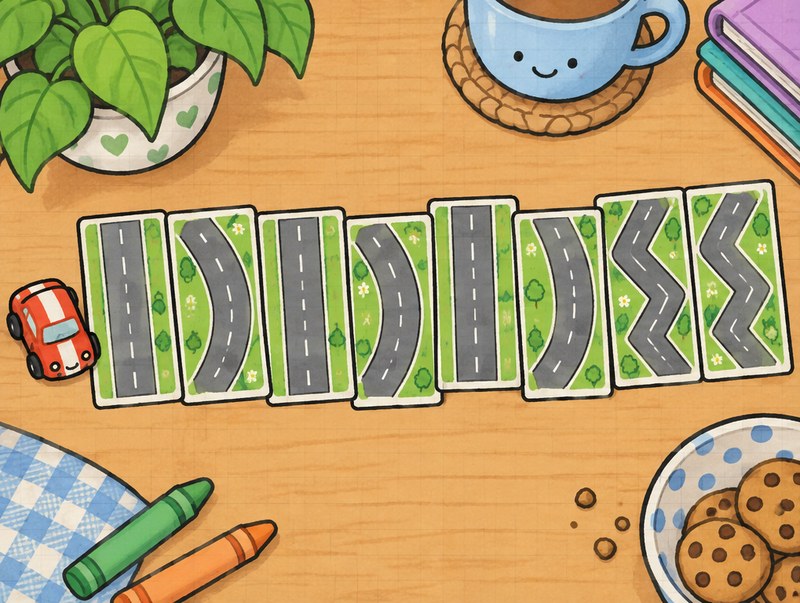
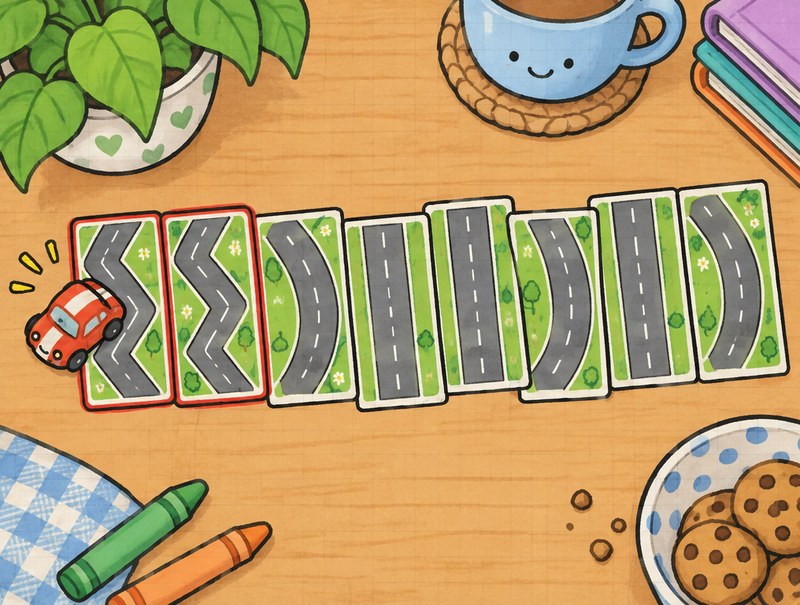
A test prioritization tool for self-driving-car simulation: a Transformer reads the full geometric sequence of each road, so failure-revealing tests run first. APFD 0.804, above the prior best of 0.781.
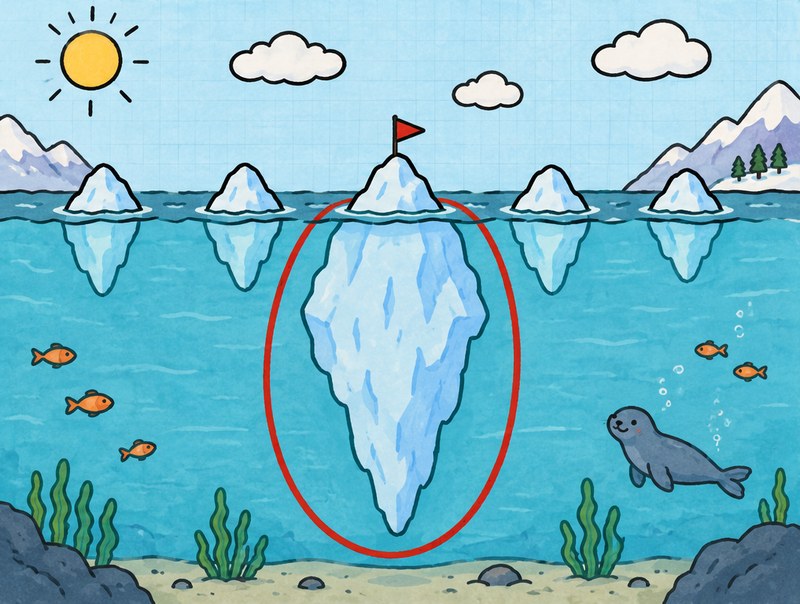
Predicts at creation time which agent-authored pull requests will cost maintainers the most review effort; flagging the top 20% catches 69% of total effort.
2nd Place, MMLoSo 2025 Language Challenge
Retrieval, LoRA-tuned NLLB and a lexical SMT branch, combined by Minimum Bayes Risk decoding for low-resource Indic translation.
2nd Place, TRACS Shared Task
Classical ML against transformer models for classifying telescope-related scientific literature.
2nd Place, ALTA 2025 Shared Task
Cascaded dual-encoder retrieval plus ontology reasoning to normalize adverse drug events to MedDRA terms.